AI compute and AI services at scale
Production AI, built around your workload
Private GPU infrastructure and ready-to-run AI services for vision, video, audio, live feeds and text.
Deploy on premises, in your cloud, in our cloud, or across a hybrid environment.
From a single GPU to 100-GPU clusters.
AI services, ready to deploy
Use our production-ready AI services or bring your own models.
Run them through APIs, batch jobs or real-time pipelines.
Video files
Audio files
Live feed
Text files
AI Medical
No two AI workloads are the same.
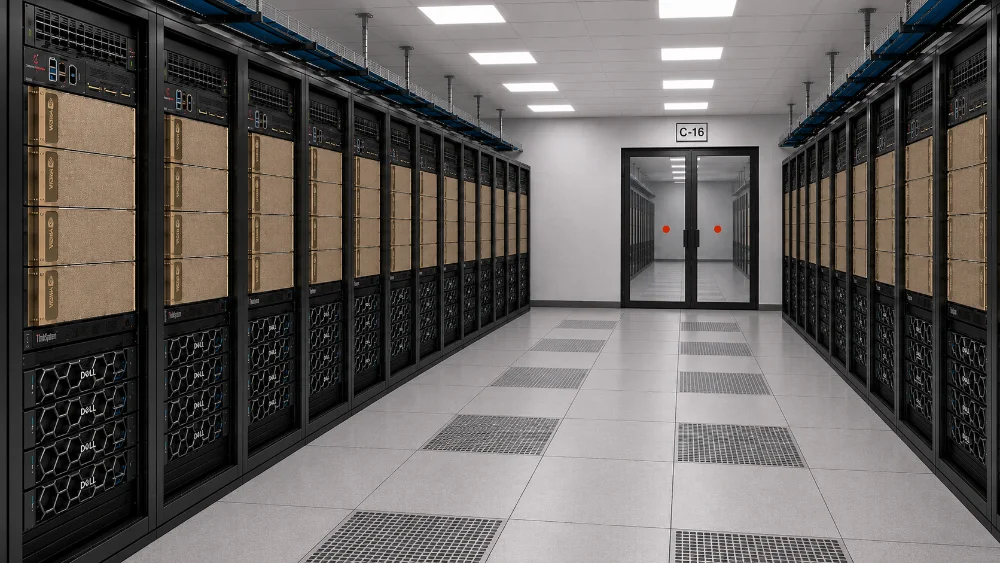
We build dedicated compute environments around your performance, security and budget requirements — combining the right GPUs, CPUs, memory, storage and networking.
Scale from one GPU to 100 GPUs, from a single inference workload to large distributed AI pipelines.
Built for:
- High throughput
- Low latency
- Large datasets
- Real-time processing
- Data privacy
- Predictable performance
Run AI where your data lives
Your infrastructure should fit your requirements — not the other way around.
Deploy the same AI workloads wherever they make the most sense.
You control where data is processed, stored and retained.
- On premises Run inside your own data center and network, including isolated and air-gapped environments.
- AWS Deploy into your AWS account and region.
- Google Cloud Deploy into your GCP project and region.
- Oracle Cloud Deploy into your OCI tenancy and region.
- Super-GPU Cloud Dedicated GPU infrastructure designed for high-scale AI workloads.
- Hybrid Keep latency-sensitive workloads local and use cloud GPU capacity when additional scale is required.
Bring your own model
Already have a model? Run it on Super-GPU infrastructure.
We help you select the right hardware, containerize and deploy the workload, build the processing pipeline and define the infrastructure required to scale it.
Your model. Your data. Your deployment choice.
Bring your existing GPU containers
We support standard Linux GPU workloads including:
- Docker
- OCI images
- NVIDIA CUDA
- vLLM
- TensorFlow
- PyTorch
and other GPU-enabled environments.
Getting your image to us
Images can be uploaded directly or pulled from registries including AWS ECR, Docker Hub, GitHub Container Registry, Google Artifact Registry, Azure Container Registry, Harbor and private registries.
From data to results
Ingest
Send files, archives, documents, video, audio or live streams through the interfaces your systems already use.
Schedule
Jobs are queued and distributed across GPU resources according to workload, priority and capacity.
Process
Run our production-ready AI models or your own models across dedicated GPU infrastructure.
Deliver
Results are returned to your applications as structured data, together with execution and processing information.
Have an AI workload that needs to scale?
Tell us what you need to process, how much data you have and where it needs to run.
We’ll help design the AI infrastructure and processing pipeline around your workload.